 Speculative Self-Distillation
Language models are routinely asked about things they never saw during pretraining: the internal documents of a company, events that happened after the training cutoff, or the vocabulary of a specialized field. The standard answer is to put the relevant text in the prompt. This works, but the document has to be processed again on every query, it competes for limited context, and models do not always make good use of evidence that is in their context. Lost in the Middle: How Language Models Use Long Contexts (Liu et al., 2024) When the same knowledge is needed repeatedly, it is more economical to train it into the weights once.
Self-distillation does this without labels or a larger model. The model is given the document and acts as a teacher; the same model without the document is the student, and it is trained to reproduce the teacher's next-token distributions. Learning by Distilling Context (Snell, Klein and Zhong, 2022) Existing methods differ mainly in who generates the text the student is trained on. Off-policy methods train on text written by the teacher, Efficient Knowledge Injection in LLMs via Self-Distillation (Kujanpää, Marttinen, Valpola and Ilin, 2025) while on-policy methods such as SDFT let the student write and use the teacher only to score each token. Self-Distillation Enables Continual Learning (Shenfeld, Damani, Hübotter and Agrawal, 2026) In standard teacher–student distillation, Speculative Knowledge Distillation (SKD) mixes the two inside a single sequence, letting the teacher replace student tokens that it considers unlikely. Speculative Knowledge Distillation: Bridging the Teacher-Student Gap Through Interleaved Sampling (Xu et al., 2025) We bring this per-token view to self-distillation. In Speculative Self-Distillation (SSD) the student writes by default and the teacher takes over only at tokens where the document changes the prediction. On three knowledge-acquisition tasks, SSD nearly matches the accuracy of on-policy self-distillation with 38–69% fewer supervised tokens, and it forgets less of the model's general ability.
Self-distillation and who writes the rollout
Let $x$ be a prompt and $C$ the privileged context, for example a document. The teacher $\pi_T(\cdot\mid x, C)$ is the base model with $C$ in its context, and the student $\pi_\theta(\cdot\mid x)$ is the same model without it. The goal is to update $\theta$ so that the student behaves like the teacher on new prompts, without being given $C$. All the methods we compare minimize the same token-level objective: On Company Memo and Wikipedia the teacher is kept frozen at the initial weights. On Science Q&A it slowly tracks the student, as an exponential moving average with rate 0.01.
where $D$ is a divergence between the two next-token distributions, such as forward KL, reverse KL or the Jensen–Shannon divergence (JSD). Divergence Measures Based on the Shannon Entropy (Lin, 1991) We use forward KL as $D$ in all experiments. What distinguishes the methods is the rollout policy $\pi_{\text{gen}}$: the model that writes the sequence $y$ on which the loss is computed.
Setting $\pi_{\text{gen}} = \pi_T$ gives off-policy self-distillation: the teacher writes the response and the student imitates it. Every position lies on a well-informed trajectory, but at test time the student has to continue from its own prefixes, which it never practiced on, a form of exposure bias familiar from imitation learning.
A Reduction of Imitation Learning and Structured Prediction to No-Regret Online Learning (Ross, Gordon and Bagnell, 2011) Setting $\pi_{\text{gen}} = \pi_\theta$ gives on-policy self-distillation: the student writes the response and the teacher scores every token of it.
On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes (Agarwal et al., 2024)
Self-Distillation Enables Continual Learning (Shenfeld, Damani, Hübotter and Agrawal, 2026)
On-Policy Distillation (Lu and Thinking Machines Lab, 2025) Training and test-time behavior then match, and on-policy training reaches higher accuracy, but it is considerably slower.
On-policy signal fades after ~15 tokens
On Wikipedia, on-policy training needed about five times more supervised tokens than off-policy to reach 78% accuracy, so we looked at where its supervision goes. The per-token loss measures how much the teacher and the student disagree at a position, and therefore how large an update that token produces; we call it the signal. On the Wikipedia task (Figure 2), the on-policy signal is high for the first ~15 tokens of each rollout and then drops to a low level for the rest of it.
Off-policy training converges faster, consistent with prior work, but on-policy training reaches a higher final accuracy. Off-policy rollouts start with more than twice the per-token signal and reduce it quickly. And along on-policy rollouts, the signal is concentrated in the first few tokens. The student writes without the document, so it soon reaches states that have little to do with it; conditioned on such a prefix, the teacher's distribution falls back to one close to the student's, and there is little left to correct.
Most of the supervised tokens in on-policy training are therefore spent on positions where the teacher adds little information.
Inflection tokens
In the example of Figure 3, asked about the marketing team of the company described in the memo, the student and the teacher agree on the opening words “Marketing team is”. At the fourth token they diverge: the teacher, which has read the memo, continues with “led by Lina Okafor”, while the student writes the generic “mainly focused on creating the …”. We call such a position an inflection position. Given a rollout and a threshold τ, position $t$ is a τ-inflection position if
where $D_{\text{switch}}$ is any divergence between the two next-token distributions.
At an inflection position the loss pushes the student strongly away from its original prediction, so after the update it is unlikely to write “mainly” in this context again. The states that follow in the on-policy rollout were generated by a policy that the update is changing, and the student will rarely visit them again. We call them transient states, and supervision on them is of limited use. On-policy training learns about each inflection position separately, over many updates, whereas an off-policy rollout contains the team lead, the team size and the remaining details in a single pass, but on text the student would not have written.
Speculative Self-Distillation
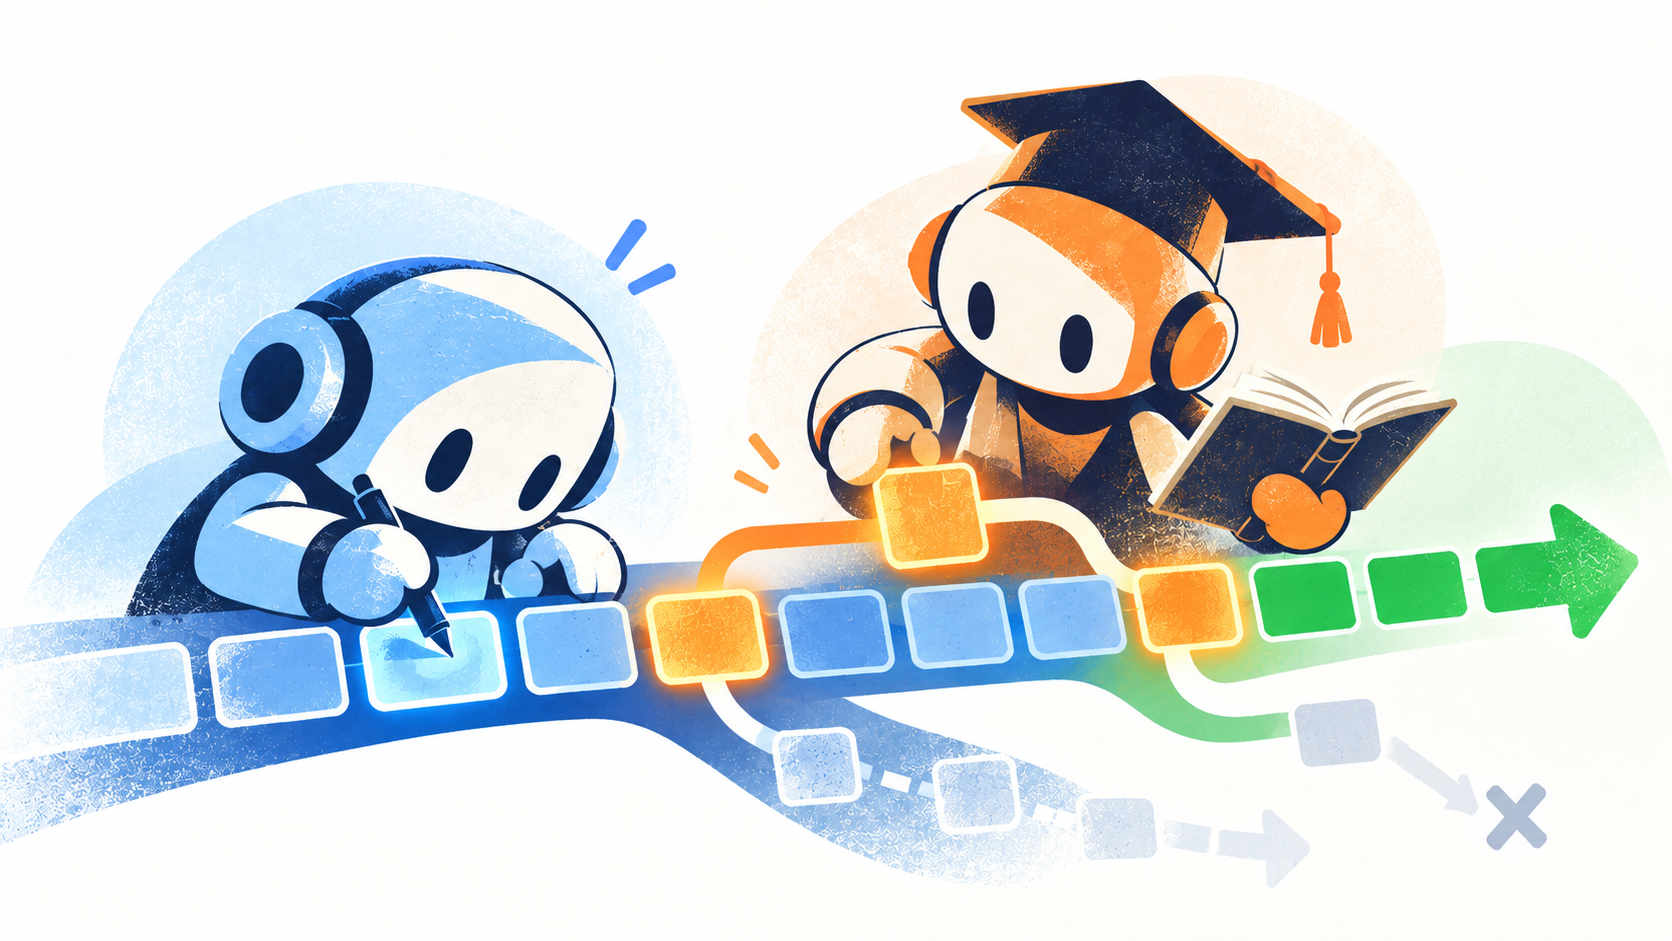
SSD keeps the rollout on the student wherever the student already agrees with the teacher, and switches to the teacher where it does not. The student generates by default. At every position both models produce their next-token distributions; if their divergence exceeds τ, the position is an inflection position and the teacher samples the token. Otherwise the student does. Every position is trained with the same loss as before, so the only change is in how the rollout is generated.
for t = 1, 2, … until EOS:
    p_S, p_T = student(x, y<t), teacher(x, C, y<t)
    if D_switch(p_T ‖ p_S) > τ:   # inflection position
        y_t ~ p_T                  # teacher writes
    else:
        y_t ~ p_S                  # student writes
    loss += D_loss(p_T ‖ p_S)      # every position is supervised
The name comes from speculative decoding, in which a small draft model proposes tokens and a larger model verifies them. Fast Inference from Transformers via Speculative Decoding (Leviathan, Kalman and Matias, 2023) Several distillation methods already switch between student and teacher inside a sequence: SKD lets the teacher replace student proposals that fall outside the teacher's top-K tokens, Speculative Knowledge Distillation: Bridging the Teacher-Student Gap Through Interleaved Sampling (Xu et al., 2025) AdaSwitch hands over to the teacher once a sliding-window KL divergence exceeds a threshold, AdaSwitch: Balancing Exploration and Guidance in Knowledge Distillation via Adaptive Switching (Peng et al., 2025) and SWITCH uses a per-position divergence criterion. SWITCH: Studying with Teacher for Knowledge Distillation of Large Language Models (Koo et al., 2025) These methods distill a separate teacher into a student. In self-distillation the two models share their weights and differ only in the privileged context, so the divergence between them indicates directly where the context changes the prediction.
The threshold τ is the only new hyperparameter. Setting τ → 0 lets the teacher write every token and recovers off-policy distillation; τ → ∞ never hands over and recovers on-policy distillation. With JSD as $D_{\text{switch}}$ the divergence is bounded by $\ln 2 \approx 0.69$, so any larger τ is exactly on-policy. The divergence used for routing need not be the one used for training: $D_{\text{switch}}$ decides who writes a token, and $D_{\text{loss}}$ trains the student.
Near on-policy accuracy with 38–69% fewer tokens
We follow the evaluation protocol of SDFT Self-Distillation Enables Continual Learning (Shenfeld, Damani, Hübotter and Agrawal, 2026) and use Qwen3-4B-Instruct-2507 as both student and teacher. The three tasks cover different reasons to internalize knowledge. Company Memo is a synthetic internal document about a fictional cooperative, standing in for private organizational knowledge. Wikipedia uses an article on Cyclone Ditwah, which postdates the model's training data and on which the base model scores below 20%. Science Q&A is the Chemistry L-3 subset of SciKnowEval, SciKnowEval: Evaluating Multi-level Scientific Knowledge of Large Language Models (Feng et al., 2024) which requires reasoning with domain knowledge rather than recalling a fact. We compare against the off-policy baselines SFT and FKL and the on-policy baseline SDFT.
We measure cost in supervised tokens, the number of response positions on which the loss is computed. This is roughly proportional to compute, and it is a fairer comparison than optimizer steps: rollout lengths differ across methods, so an optimizer step does not cost the same in each.
Supervised tokens do not capture everything. SSD needs the teacher's next-token distribution at every decoding step, whereas on-policy training can score a finished rollout with a single parallel teacher pass. We run the teacher and the student concurrently in a modified vLLM engine, with the teacher on a second GPU, and a joint decoding step runs at about 92% of the speed of a student-only step. On Science Q&A, SSD reaches the best on-policy accuracy after about 130 minutes of training, against about 414 minutes for on-policy training.
The baselines show the same trade-off. Off-policy training improves quickly but levels off below SSD and on-policy on Wikipedia and Science Q&A, and close to SSD on Company Memo; on-policy training reaches a higher plateau only after much more supervision. SSD reaches the best on-policy accuracy with 38% fewer supervised tokens on Wikipedia and 69% fewer on Science Q&A. On Company Memo it comes within 1.4 points of it with 48% fewer, so across the three tasks SSD stays close to on-policy accuracy while using 38–69% fewer supervised tokens.
One knob from off- to on-policy
Figure 5 sweeps the threshold on Company Memo. At small τ the teacher intervenes often: few tokens are supervised and final accuracy is close to off-policy. As τ grows, more of each rollout is written by the student, and accuracy rises toward the on-policy level along with the cost. Intermediate thresholds reach higher accuracy than off-policy while using fewer supervised tokens than on-policy, so SSD traces a Pareto frontier between the two.
The teacher steps back on its own
SSD has no schedule for how much the teacher participates, and Figure 6 shows that none is needed. Early in training the student and the teacher disagree at many positions, and the teacher writes a large share of each rollout, up to 43% of tokens at the lowest threshold. As the student learns the document, the switch fires less often and teacher involvement decays for every threshold.
Response lengths follow the same pattern. With a high threshold the student keeps control for longer and drifts further from the teacher's distribution, so early rollouts are long and variable. As training proceeds, lengths settle and converge across thresholds. The teacher is used heavily while the student lacks the knowledge, and its share falls as the student learns, until training is close to on-policy.
It also forgets less
We also measure how much each method degrades the model's general capabilities. SDFT showed that on-policy self-distillation forgets less than supervised fine-tuning, Self-Distillation Enables Continual Learning (Shenfeld, Damani, Hübotter and Agrawal, 2026) and because SSD keeps rollouts close to the student's distribution we expected it to share this property. With Qwen3-4B we saw little forgetting under any method, likely because the model was already post-trained on data resembling the evaluation suite. We therefore follow the SDFT protocol and fine-tune Qwen2.5-7B-Instruct on SciKnowEval chemistry, measuring in-domain accuracy against the average change on six general benchmarks.
The off-policy methods SFT and FKL learn the new skill but lose about 6.6 points on the general benchmarks. On-policy SDFT loses 4.5 while reaching higher in-domain accuracy. SSD has both the highest in-domain accuracy (73.5, against 71.0 for SDFT) and the smallest loss (−1.4), while using 23% fewer supervised tokens than SDFT.
Citation
@inproceedings{talaei2026ssd,
  title     = {Speculative Self-Distillation enables
               Efficient Knowledge Internalization},
  author    = {Talaei, Shayan and Bhatia, Agam and Soltani Moakhar, Arshia and
               H{\"u}botter, Jonas and Saberi, Amin and Mirhoseini, Azalia},
  booktitle = {Advances in Neural Information Processing Systems},
  year      = {2026}
}